Get your data AI‑ready in 14 days.
We turn your PDFs, databases and APIs into one store your RAG and agents answer correctly from. Then we prove it on 50 of your own questions.
€2,900 fixed · 14 days · if your questions don’t pass, you don’t pay the second half
Prefer to talk now? +48 517 773 822Built on 15 years of production data work for a European payments group in 25 countries, a 2,000-store fashion retailer and a global FMCG brand. See the case studies
From scattered sources to one store your AI can trust.
Most AI features break in production for one reason: the demo ran on a clean extract, the product runs on the real mess. We fix the mess.
# invoice_0417.pdf (OCR)
ACME Sp. z o.o.   NIP 123-456-32-18
Faktura nr FV/04/17   Data: 17.04.24
Razem brutto:   12 300,00 zł

# crm_export.csv
"Acme sp z oo",1234563218,
"ACME Sp. z o.o. ",PL 123 456 32 18,

# support_ticket_8812.eml
"…the Acme order from April was wrong…"
{
  "entity_id": "org_1234563218",
  "name": "ACME Sp. z o.o.",
  "tax_id": "PL1234563218",
  "invoices": [{ "no": "FV/04/17",
    "date": "2024-04-17", "gross": 12300.00,
    "currency": "PLN" }],
  "tickets": ["8812"],
  "source": ["pdf", "crm", "email"],
  "embedding": "text-embedding, 1536d"
}
Find
We pull data from where it really lives: your database, file shares, SaaS exports, registries, the web.
Clean
Parse PDFs and scans, merge duplicates, normalise dates, amounts and IDs. Personal data is masked first.
Store
Tables plus a vector index, tagged so retrieval can filter by customer, date or document type.
Prove
Your test questions run against the store. You see the score before and after.
One use case, 14 days, a fixed price.
Small enough to start this month. Real enough to show whether it works on your data.
Scope and test set
We agree on one use case, up to 3 data sources and 50 test questions with expected answers. These questions are the acceptance criteria.
Build the pipeline
Extraction, cleaning, entity matching and loading into the store. A short written update every day.
Evaluate and tune
We run the test set, fix what fails and report the score per question.
Handover
- Pipeline code in your repository
- Populated store and index
- Evaluation report and test set
- A 60-minute walkthrough for your team
The pilot
One use case, up to 3 sources.
- Payment
- 50% at kickoff, 50% on acceptance.
- Acceptance
- Your test set reaches the score we agree on day 2.
- If we miss it
- We keep working for up to 10 more days at no cost. Still missed? You don’t pay the second half.
- Security
- NDA before access. Data stays in the EU or in your own cloud.
From pilot to production, on the tools you already run.
Most teams start with the pilot. Some begin with an audit, and the ones that ship keep us to run it.
Audit
What data you have, what is missing or risky, and a costed plan.
Pilot
One use case working on your data, accepted on your questions.
Build
All sources, automatic refresh, monitoring and tests on every release.
Run
We keep data, index and tests fresh as your product changes.
Works with your stack
| Sources | Postgres and MySQL, Salesforce, HubSpot, SharePoint, PDFs and scans, SAP |
|---|---|
| Pipelines | Python, dbt, Airflow, Airbyte |
| Storage | BigQuery, Snowflake, Databricks, Postgres with pgvector |
| AI layer | Pinecone, Qdrant, LlamaIndex, LangChain, MCP servers for agents |
| Quality | Ragas, Langfuse, Great Expectations |
Full tool list
Ingestion: Airbyte, Fivetran, dlt, Kafka, REST and GraphQL APIs, webhooks, web data (Playwright, Apify), public registries, Google Drive, SharePoint, email, Salesforce, HubSpot.
Documents: Unstructured, LlamaParse, Docling, Google Document AI, Azure Document Intelligence, OCR, Whisper for audio.
Transform and quality: dbt, SQLMesh, Great Expectations, Soda, Splink for entity resolution, Presidio for PII, data contracts.
Warehouses: BigQuery, Snowflake, Databricks, PostgreSQL, Apache Iceberg, Microsoft Fabric, SAP Datasphere, SAP BW/4HANA.
Retrieval: pgvector, Pinecone, Weaviate, Qdrant, Elasticsearch and OpenSearch hybrid search, rerankers, Neo4j knowledge graphs, OpenAI, Cohere, Voyage and open-source embeddings.
Orchestration: Airflow, Dagster, Prefect, GitHub Actions, Make and n8n. Evaluation: Ragas, DeepEval, Langfuse, Arize Phoenix. Clouds and BI: Google Cloud, AWS, Azure, Power BI, Tableau, Looker, SAP Analytics Cloud.
Data stuck in SAP?
Most of our founder’s 15 years in data has been on SAP: BW, and now S/4HANA and BW/4HANA. We get sales, finance and supply-chain data out to your AI stack with the business meaning intact.
15 years of production data work.
The groundwork AI features depend on: getting data out of many systems, modelling it, testing it and keeping it fresh.
Runs the data flow from the ERP into retail analytics, plus buying-plan and financial reporting on top. New development and incident fixing in one backlog.
Sales, materials and CRM data models for reporting across markets, plus third-line support for production data flows. 100% of incidents resolved.
ETL flows for North America waste reporting with Tableau on top. After go-live, waste-reporting execution went up 25%.
ELT on BigQuery: Python loaders, dbt models with data tests, Airflow scheduling, releases through GitHub.
Marketing analytics end to end: several source systems into BigQuery, a warehouse model and management dashboards, with a team of up to 4.
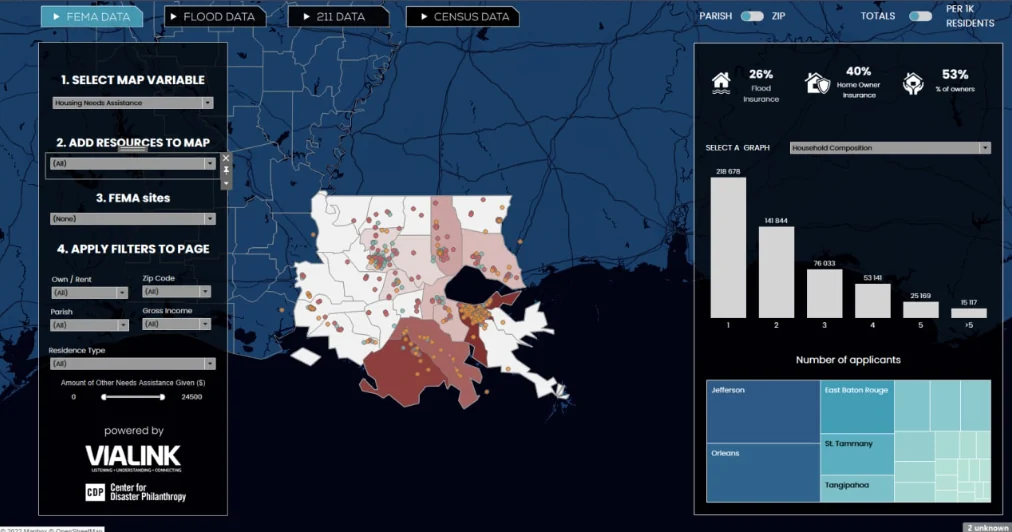
FEMA programme, flood and Census data combined into one database and five geo-tagged dashboards for disaster-management teams.
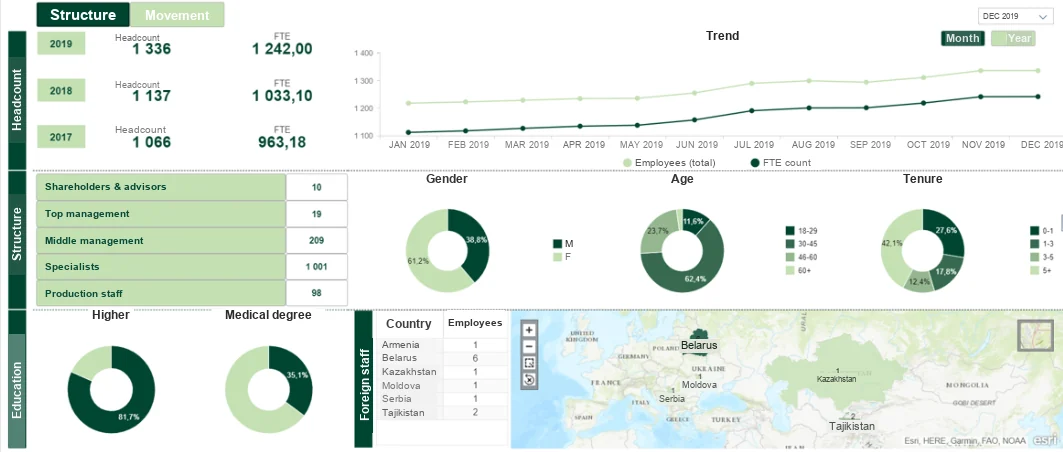
Moved reporting from Azure and Power BI to a new warehouse and cloud analytics. Marketing, manufacturing, procurement and HR reporting across several go-lives.
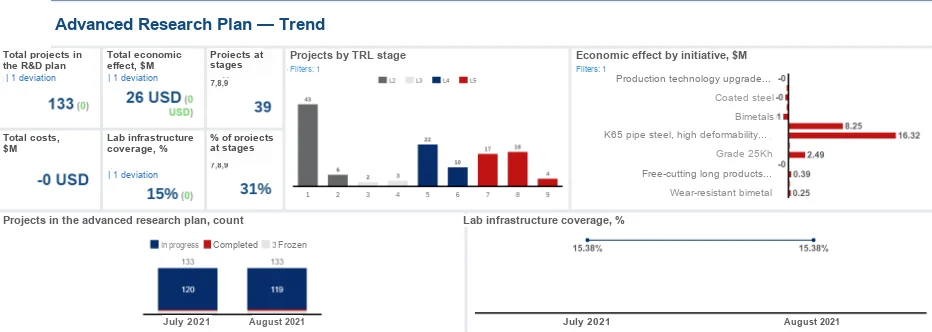
Innovation-portfolio dashboards: projects by technology readiness level, economic effect per initiative and lab capacity, from project systems into one view.
Static Excel reports replaced with interactive dashboards: budget in money and copies, revenue plan vs. delivered orders, price deviation by product line.
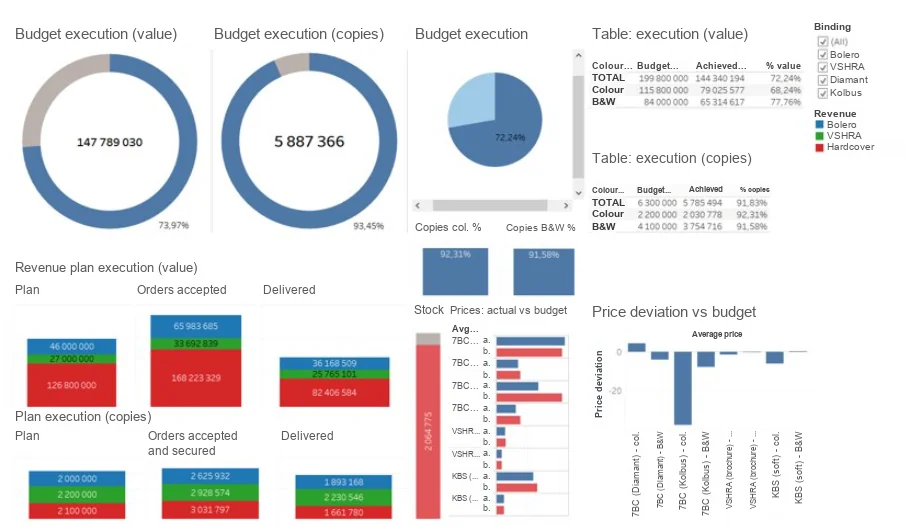
Also: sales and material-movement reporting for a manufacturer, with reporting efficiency up about 50% after go-live. Screenshots are real client dashboards with labels translated to English. Client names are removed, except VIA LINK, a non-profit that publishes its dashboards. References on request.
Who you’ll work with
Mikhail Mukhanov, founder of Datalift, senior data engineer and architect
15 years in data warehousing, pipelines and BI, leading teams of up to 15. Data integration, data quality and moving legacy reporting to the cloud for retail, FMCG, fintech, pharma and manufacturing. Four SAP certifications.
Who this is for.
Good fit
- Seed to Series B AI startups whose product answers from customer or domain data
- Teams whose demo works but production answers are wrong or out of date
- Engineers busy on the product who need the data layer done properly, fast
- Products that need European data: Polish and CEE registries, documents, languages
- Companies whose key data lives in SAP and needs to reach an AI or analytics stack
Not a fit
- Training foundation models from scratch
- Data labelling at scale
- Projects without a concrete use case yet: start with the free call instead
- Defence and political-campaign work
Before you book.
Why a fixed price? What if our data is bigger than expected?
The pilot is scoped to one use case and up to 3 sources, so the price can be fixed. We check the scope on the free call, before you pay anything. If on day 2 it still turns out bigger, you choose: a smaller scope at the same price, or a separate quote for the rest.
How soon can you start?
Usually within a week of the call. The 14 days start once we have access to the sources and the test set is agreed.
How do contracts and invoicing work?
A short services agreement with an NDA and a data processing agreement. We invoice in EUR or USD from Poland, EU VAT rules apply. 50% at kickoff, 50% on acceptance.
Who owns the code and the data?
You do. Everything goes into your repository and your infrastructure. We keep no copy after handover unless you ask us to maintain it.
How do you handle sensitive data?
We sign an NDA and a data processing agreement before we get access. We prefer working inside your cloud account; otherwise data is processed in the EU and deleted after handover. Personal data is masked before it reaches any vector index.
Which stack do you use?
Whatever you already run. For a pilot our default is Python, dbt and Airflow with Postgres and pgvector or BigQuery, because it is cheap and easy to hand over.
What happens after the pilot?
Either your team runs it, using the walkthrough and the code we hand over, or we keep the pipeline fresh on a monthly retainer. No lock-in either way.
Where are you based?
Warsaw, Poland. We work in English with teams in the EU, the UK and the US, and overlap with US East Coast mornings.